Claude Code 团队如何进行代码审查
原文:How the Claude Code team does code review | 作者:Addy Osmani | 日期:2026-10-26
📝 摘要
随着 AI 编程智能体的广泛应用,代码生成速度呈指数级爆发,传统的逐行人工代码审查已难以为继。在 Claude 编写了自身约 90% 代码的背景下,Claude Code 团队系统性重构了代码审查体系:将代码审查从传统的「事后卡点」转变为编写过程中的「持续拼写检查」,构建了涵盖 PR 提交前本地验证、AI 自动化多智能体初审、具备一票否决权的安全审查、CI 拦截、按风险阶梯化的人工审批、合并队列(Merge Queue)与特性标记在内的六层纵深防御体系。此外,团队将历史真实事故沉淀为日常回归评测集(Evals),针对智能体作者与智能体审查器之间可能陷入的无限死循环发明了「收敛机制」(Convergence),并坚持「谁合入,谁负责」的工程文化。在 6 月至 9 月间,团队合并 PR 数量翻倍,而代码回滚率却下降超过 40%,成功跑通了一套在人机协作大规模编码时代行之有效的高效审查范式。
📋 术语表
| 英文 | 中文 | 说明 |
|---|---|---|
| code review | 代码审查 | 对源代码进行人工或自动化检查以发现缺陷并增进代码理解的过程 |
| monorepo | 单仓库 | 将组织内多个项目集中管理在单一代码仓库中的工程模式 |
| merge queue | 合并队列 | 在主干分支按序对排队代码执行集成测试,避免因并发合入导致主干损坏的 CI 机制 |
| feature flag | 特性标记 | 在运行时动态开启或关闭特定功能的技术,支持解耦代码部署与业务发布 |
| staged rollout | 分阶段发布 | 将新版本先推向内测和灰度群体、再逐步放量至稳定全量用户的发布策略 |
| blast radius | 爆炸半径 | 某项代码变更或系统故障可能波及和损坏的业务与系统范围 |
| evals | 评测 / 评估 | 用系统化标注或历史事故数据集量化模型与代码审查准确率的测试基准 |
| circuit breaker | 熔断机制 | 当异常或事故率超过阈值时自动切断操作或提高审查门槛的自适应保护机制 |
| subagent | 子智能体 | 由主智能体派生、在独立全新上下文窗口中执行特定检查或探索的小型智能体 |
| revert rate | 代码回滚率 | 已合入主干的代码由于缺陷或故障被迫执行撤销回滚的 PR 比例 |
| git blame | git blame | 查看代码文件中每一行最后修改者和提交历史的 Git 命令 |
| CODEOWNERS | CODEOWNERS | 代码仓库中用于定义特定文件或目录责任人并在 PR 时自动请求审查的配置文件 |
正文(双语对照)
We previously mentioned that Claude writes about 90 percent of the code for Claude Code. So how do we do code review at this scale? Who reads code anyway? What happens if code goes wrong?
我们此前曾提到,Claude 编写了 Claude Code 项目中约 90% 的代码。那么,在如此庞大的代码规模下,我们该如何进行代码审查?到底还有谁在读代码?如果代码出了纰漏,又该如何处理?
This post describes our team’s code review process at Claude Code and how we have improved it. Between June and September, we saw more than double the number of pull requests that were merged to the codebase for Claude Code, while the share of pull requests that had to be reverted fell by more than 40 percent.
本文将深入介绍 Claude Code 团队的代码审查流程以及我们是如何对其进行迭代优化的。在今年 6 月至 9 月期间,合入 Claude Code 代码库的 Pull Request(PR)数量翻了一倍多,而不得不回滚的 PR 比例却下降了 40% 以上。
We didn’t stop doing code review. Instead, we’ve automated the majority of reading and tuned it to optimize for human time and effort. We’ve also made significant investments into improving the speed and ease of reverting mistakes.
我们并没有放弃代码审查。相反,我们将绝大部分阅读代码的工作自动化,并对其进行精细调优,最大程度节省人类开发者的时间与精力。同时,我们还投入重金与工程力量,大幅提升了错误回滚的速度与便捷性。
重新思考代码审查的目标
With agents writing code, the volume of changes increases rapidly. In our monorepo, we went from approximately 2,500 changes merging each day in May to over 30,000 in September of this year.
随着智能体开始编写代码,代码变更的吞吐量呈现爆发式增长。在我们的单仓库(Monorepo)中,每日合入的代码变更从 5 月份的约 2,500 次跃升至今年 9 月份的 30,000 多次。
While Claude Code is not in our monorepo, it has a lot of pressure on it as well. When you’re moving fast like that, it becomes increasingly hard, if not impossible, to do code review manually, line by line.
尽管 Claude Code 本身不在这个单仓库中,但它同样承受着极高的发布与迭代压力。在如此飞快的迭代节奏下,逐行依靠人工手动审查代码即使不算完全不可能,也变得越来越难以维系。
Code review serves two purposes:
代码审查的核心目的有两个:
-
Detect and correct bugs before they ship
-
在代码发布上线前发现并修正 Bug
-
Develop a shared understanding of the codebase
-
建立团队对代码库的共同理解与上下文同步
While this article focuses primarily on the first goal, we’ll discuss the second goal toward the end of the post.
本文将主要聚焦于第一个目标,并在文章后半部分深入探讨第二个目标。
We view “did someone read the code?” as an imprecise measure of “what could go wrong with this change, and what check - automated or human - is the right one to catch it?”
在我们看来,「是否有人读过这些代码?」对于「这次变更可能会引发什么问题,以及到底该用何种检查(自动化还是人工)来准确捕获它?」而言,是一个极其粗糙且不精确的衡量指标。
This question also changed the timing of code review. Traditionally, code review was a check performed after the fact, when the code was written, the PR was filed, and someone waited for someone else to take a look. Instead, we’ve integrated code review into the workflow. It’s more like a spellcheck that you continuously do while writing.
这一认知也彻底改变了代码审查的时机。在传统模式中,代码审查是一项事后检查:代码写完、PR 提交,然后作者干等其他人抽出时间来审阅。而在我们的实践中,代码审查被深度整合到了整个工作流当中,它更像是在你边写字时边实时运行的拼写检查器(spellcheck)。
The majority of changes have already been reviewed and corrected by Claude, at least once, before a human is asked to take a look. In this way, we catch most of the routine bugs and reserve human attention for more high-level considerations.
在请求人工介入审阅之前,绝大多数变更其实已经至少被 Claude 自身审查并修正过一轮了。通过这种方式,我们拦截了绝大部分常规缺陷,从而将人类宝贵的注意力保留给更高维度的考量。
人类的时间与注意力
We want to reserve human time and attention for things only humans can handle, while making sure we have enough automation to cover the rest. Even at our current pace, there is still an incredible amount of work for humans to do, and our team is encountering new and novel challenges almost every day.
我们的核心诉求是将人类的时间和注意力留给那些唯有人类才能胜任的事情,同时构建足够强健的自动化体系来兜底其余部分。即便在当前的研发节奏下,人类依然有海量工作要做,我们的团队几乎每天都在迎战层出不穷的新挑战。
For this reason, human time is a dual-sided cost. Not only do we count the time people spend doing code review, but also the time that they spend fixing bugs that are introduced by bad code. If we reduce the first without reducing the second, we’re not really saving human time.
正因如此,人类的时间是一项双重成本。我们不仅要计算大家花在代码审查上的时间,更要计算后续排查修复因劣质代码引入的 Bug 所耗费的时间。如果仅仅压减了前者却放任后者激增,那根本算不上真正节省了人类的时间。
So, our goal is that the majority of pull requests in our Claude Code repos (the CLI, the desktop and web apps, and the mobile apps) should merge with a maximum of one person in the loop (who could be the author) without an increase in reverts or incidents.
因此,我们的终极目标是:在 Claude Code 相关的各个仓库(包括 CLI、桌面与 Web 应用以及移动端应用)中,绝大多数 Pull Request 在最多只需一人参与(此人甚至可以是作者本人)的情况下即可合入,同时回滚率和事故数绝不增加。
We track our human time in terms of median human approvals per PR (along with the 95th percentile), the number of human comments, and how long a PR waits on a person. We use the revert and incident rates as a guardrail: if these metrics increase, we haven’t reduced human time, just relocated it.
我们通过单 PR 人工审批中位数(以及 P95 分位数)、人工评论数量以及 PR 等待人工响应的时长来追踪人类时间的消耗。与此同时,我们将代码回滚率和线上事故率设为关键护栏指标:一旦这些指标上升,说明我们根本没有减少人类的工作量,仅仅是将精力转移到了更痛苦的救火中。
一次变更的生命旅程
A typical change, whether it’s from an engineer’s laptop or a Claude session in Slack, goes through multiple layers of review.
一次典型的代码变更——无论它发端于工程师的笔记本电脑,还是 Slack 中的 Claude 会话——都会历经多层细致的审查。
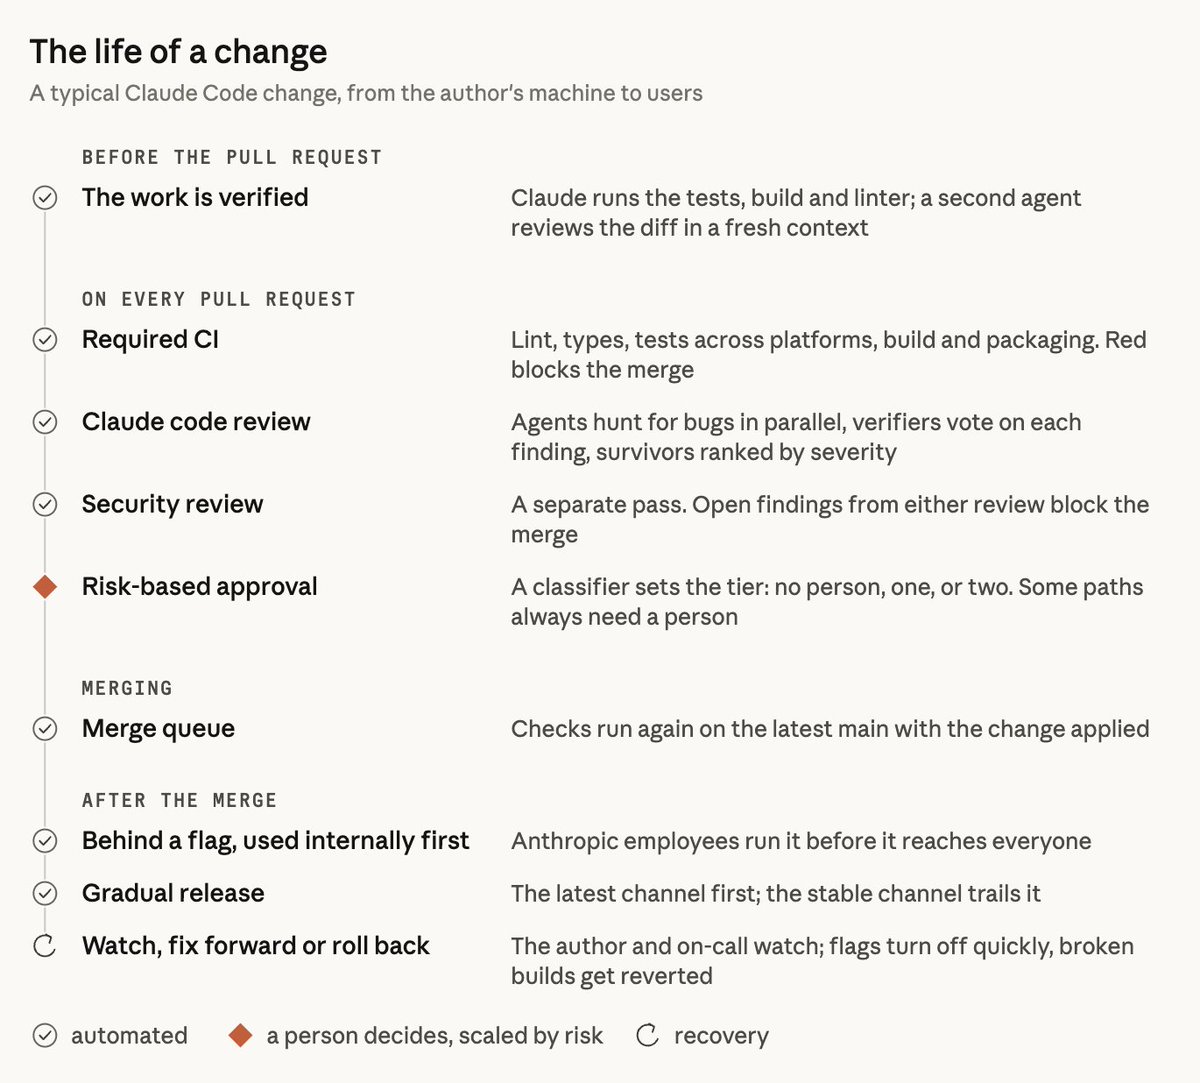
图 A:一次变更的生命旅程(FIG A: The life of a change)
Above is the typical Claude Code change, from the author’s environment to production. Most of this process is automated, with human attention focused on the risky part.
上图展示了 Claude Code 典型的变更流转全景:从代码作者的环境一路直达生产环境。其中绝大部分流程已完全自动化,人类的注意力只牢牢钉在最高风险的环节上。
We have six layers of checks with a rollback mechanism to handle any issues that get through.
我们构筑了六层严密的检查关卡,并辅以回滚机制来托底任何可能侥幸漏网的问题。
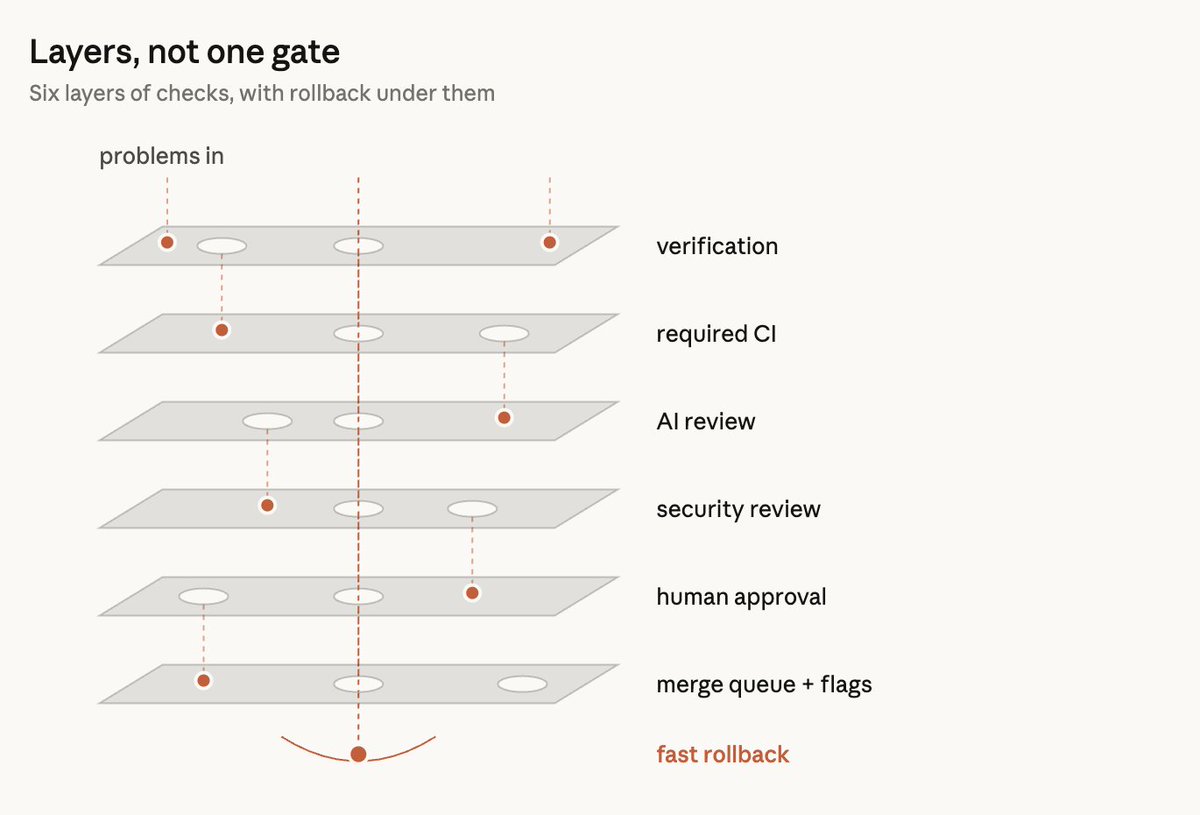
图 B:多层纵深防御,而非单一卡点(FIG B: Layers, not one gate)
Each layer catches some bugs while missing others. Few bugs get through all of the layers, and if some do, we have a rollback mechanism in place.
每一层防护都能捕获特定类型的 Bug,同时难免放过其他类型。极少有 Bug 能够穿透全部六层防线;而万一真的穿透了,我们完备的回滚机制也会迅速兜底。
1. PR 提交前验证(Pre-PR verification)
Most of our review is done before we create a PR. We ask Claude to do something runnable, such as running tests, the build, or comparing a screenshot to the design. Instead of saying the task is done, we ask it to show us the result. Then, a subagent reviews the diff with fresh context. Both these strategies are part of our guide to best practices.
我们的大部分审查其实在创建 PR 之前就已经完成了。我们会要求 Claude 执行可运行的操作,比如运行测试、执行构建,或者将页面截图与设计稿进行比对。我们不会让它仅仅口头回复「任务完成」,而是要求它把执行结果直接展示出来。随后,一个拥有全新无污染上下文的子智能体(subagent)会审阅这份 diff。这两种策略都收录在我们的最佳实践指南中。
Before opening a PR, many of us also run a handful of internal skills — bug hunting, diff reduction, end-to-end validation, and checking our UI changes against our design guidelines.
在正式提交 PR 之前,我们团队的很多人还会运行几个内部的 Agent 技能(skills)——比如 Bug 排查(bug hunting)、差异精简(diff reduction)、端到端验证以及对照设计规范检查 UI 改动。
According to Boris Cherny, who created Claude Code, equipping Claude with a verification process is probably the biggest key to higher quality outcomes.
按照 Claude Code 的创造者 Boris Cherny 的说法,为 Claude 配备一套完备的验证流程,或许是获取更高质量交付成果的最关键钥匙。
He estimates that a verification process improves the quality of Claude’s output by a factor of two to three.
他评估认为,一套严密的验证流程能将 Claude 的输出质量提升两到三倍。
The verification process for any given domain can be very different:
针对不同业务领域的验证流程可能大相径庭:
Sometimes it’s as simple as running a bash command. Sometimes it’s running a test suite. Sometimes it’s testing the app in a browser or phone simulator.
有时它就像执行一条 bash 命令那样简单;有时是运行一整套测试套件;有时则是在真实浏览器或手机模拟器中全面测试应用。
If the automated reviewer is consistently flagging the same issue, we fix it at the source — via the skill itself, a lint rule, or updating documentation files like:
如果自动化审查器持续指出同类问题,我们就会从源头修复——要么优化技能本身、要么新增一条 lint 规则,要么更新如下核心规范文档:
CLAUDE.md — The project description file that you can use to give Claude context about the project (technology stack, conventions, goals, non-goals). Claude Code pulls this file in for every single review, so we keep it brief for large codebases and reference the rest of the documentation here. When code breaks a convention in this file, or an update makes something in it out of date, the reviewer flags it.
CLAUDE.md —— 这是用于为 Claude 提供项目全局上下文的项目描述文件(包括技术栈、编码规范、目标与非目标)。Claude Code 在执行每一次代码审查时都会拉取该文件,因此对于大型代码库,我们尽量保持其简明扼要,并在此引用其余详细文档。当代码违反了该文件中的约定,或者某项更新导致文件中的描述过时时,审查器就会直接提出警告。
REVIEW.md — The file where code owners tell the reviewer what matters in their part of the code. We separately verify whether the reviewer is actually following these guidelines. Good ones are brief and focus on:
REVIEW.md —— 这是各模块代码所有者(Code Owner)向审查器交代该部分代码关注重点的文件。我们会单独验证审查器是否切实遵循了这些准则。一份优秀的 REVIEW.md 往往篇幅简炼,且核心聚焦于:
Defining project failure (the docs should not lie; the config should not misroute) Limiting nitpicking Defining ignored paths Requiring file + line reference, not guessing filenames Requiring top-level summary including count and clear statement of “no issues”
明确定义何谓项目失败(如文档绝不能说谎;配置绝不能路由错误);限制细枝末节的琐碎苛责;明确界定需要忽略的文件路径;强制要求给出具体文件名加行号引用,杜绝臆测文件名;强制要求提供包含问题计数和明确声明「未发现问题」的高层摘要。
2. 针对每个 Pull Request 的 AI 审查
Every PR receives a Claude review before a human review.
每一个 PR 在进入人工审查之前,都会先接受一次 Claude 的全面审查。
The diff is analyzed against the entire codebase and the intent of the PR as stated by the PR author. It checks that: the change actually addresses the issue the change fits into the larger system the change does not break other parts of the codebase
系统会结合整个代码库以及 PR 作者所阐述的意图来深入分析 diff。它重点检查:变更是否真正解决了目标问题、变更是否契合更大维度的系统架构、变更是否会破坏代码库的其他部分。
When reviewing a bug fix, the bot tries to find the root cause.
在审阅 Bug 修复类型的 PR 时,机器人会尝试探寻深层的根本原因(root cause)。
Our public product, Code Review for Claude Code, is now available to all Team and Enterprise customers. There is a lighter version for local use as well — /code-review.
我们的对外商业化产品 Code Review for Claude Code 现已面向所有 Team 与 Enterprise 客户开放。此外,还有一个可供本地使用的轻量版本——/code-review 命令。
Since we released the research preview, the share of our internal PRs getting substantive review comments has gone from 16% to 54%. Code Review detects issues on the majority of PRs with more than 1,000 lines and returns clean results on most smaller PRs. Repos can be configured by admins to use Quick, Standard, or Deep modes. Deep is useful in cases where the cost of missing a single bug is higher than the time spent reviewing code.
自从我们发布研究预览版以来,团队内部获得实质性审查意见的 PR 比例从 16% 飙升至 54%。对于超过 1,000 行的大型 PR,Code Review 能精准侦测出绝大多数潜在问题;而对于大多数较小的 PR,它则能干净利落地快速放行。管理员可将仓库配置为 Quick(快速)、Standard(标准)或 Deep(深度)三种模式。在漏掉单个 Bug 的代价远高于审查代码耗时的关键场景下,Deep 模式极其有用。
Findings are vetted by multiple other agents before human review:
在呈现给人工审阅之前,所有审查发现的问题都会先由其他多个智能体交叉审核验证:
-
Multiple agents run in parallel to hunt for bugs
-
多个智能体并行运转,联合排查 Bug
-
A separate vote decides if a finding is valid or a false positive, only confirming the findings that have enough votes
-
通过独立的投票机制判定某项发现属于有效 Bug 还是误报(false positive),只有获得足够票数的问题才会最终被确认
-
Findings that are only style/diagnostics/cleanup related are filtered out (we A/B tested these filters on our own PRs before rolling them out)
-
纯粹涉及代码风格、诊断日志或细枝末节清理的琐碎意见会被自动过滤掉(在全量推行之前,我们在团队内部的 PR 上对这些过滤器进行了充分的 A/B 测试)
The remaining findings are presented as inline comments, ordered by severity level and marked as:
最终筛选出的有效问题会以行内评论(inline comments)的形式呈现,按照严重程度排序并标记为:
Important Nit Pre-existing (so we don’t unfairly penalize the author for bugs that were not introduced by the PR)
重要(Important)、细节(Nit)、既有存量问题(Pre-existing,避免作者因并非由本次 PR 引入的陈年旧疾而受到不公苛责)
All findings must be addressed — fixed or the thread is resolved with a reason. In many cases, an agent will fix the problem overnight so the author returns to a PR that’s already been through another review pass.
所有提出的问题都必须得到处置——要么完成修复,要么附上合理解释关闭讨论线程。在很多情况下,智能体会连夜自动把问题修复好,作者第二天回到工作岗位时,看到的已经是一个经历过新一轮审查并修正完毕的清爽 PR。
3. 具备一票否决权的安全审查
We also run an automated security review. No PR can be merged while there is still an open finding (either from the code review or the security review). The author can either fix the issue or close the thread with a short reason (how we deal with a false positive).
我们还会运行一套自动化的安全审查。只要存在尚未解决的未决项(无论是来自代码审查还是安全审查),任何 PR 都绝对无法合入。作者既可以直接修复漏洞,也可以附上一段简要理由关闭讨论线程(这也是我们应对误报的标准机制)。
A finding will be auto-closed if a subsequent commit addresses the problem. You can set up the same thing with the open-source security review GitHub Action, or the /security-review command. See automated security reviews in Claude Code for a guide on how to set this up.
如果后续提交成功解决了该问题,系统会自动将该项标记为已关闭。你也可以通过开源的安全审查 GitHub Action 或 /security-review 命令搭建完全相同的机制。具体配置可参考 Claude Code 中的自动化安全审查指南。
4. 具备拦截作用的自动化检查
Standard checks: lint, type checks, tests on all platforms, build. (We wrote about how we scaled CI here.) A typical CLI PR can have dozens of checks run before anyone looks at it. The PR template has questions about how the change was tested and how to revert it. Claude can answer those for you, but the author is responsible for reviewing them.
标准流水线检查包括:代码风格规范(lint)、类型检查(type checks)、全平台自动化测试以及项目构建。(我们此前曾撰文介绍过团队是如何扩展 CI 基础设施的。)一个典型的 CLI PR 在任何人点开阅读之前,就已经先跑了数十项自动化检查。PR 模板中包含两道必答题:本次改动是如何测试的?万一出问题该如何回滚?Claude 可以帮你起草这些答案,但作者本人必须亲自审阅并对此负责。
5. 按风险等级阶梯化的人工审批
Some changes are more risky than others (e.g. a docs fix vs. an auto-updater change), so they require different levels of review.
代码变更之间的风险不可同日而语(例如,仅仅修复文档错别字与修改自动更新模块之间风险天差地别),因此它们需要匹配不同力度的审查级别。
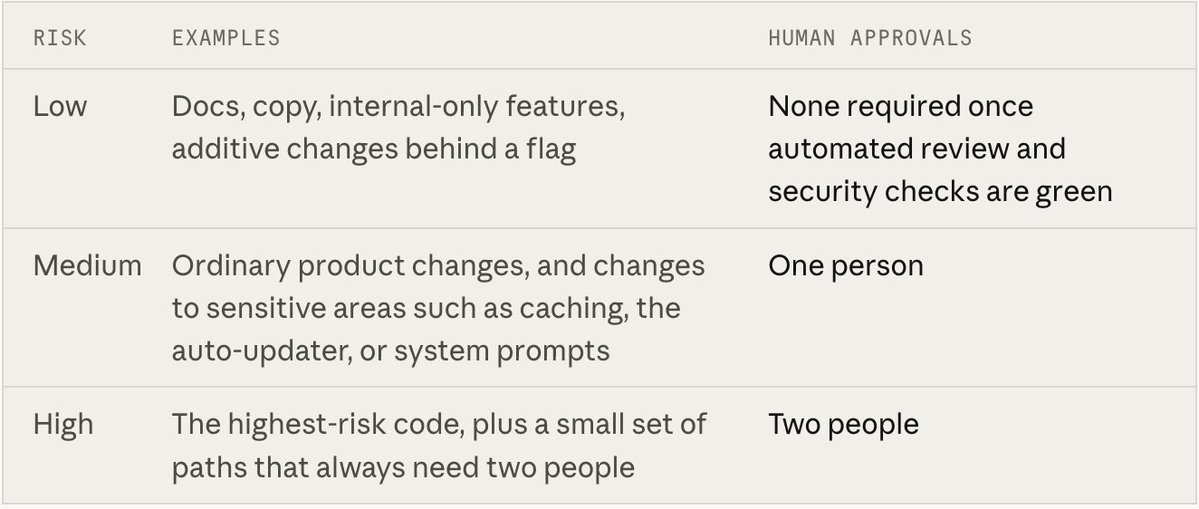
图 C:按风险梯级划分的审批矩阵(FIG C: Risk tiers)
The tier is determined by the change, not the author. A classifier determines the risk level based on the change. Another classifier determines if a particular change actually requires another approval, even if the tier does not say it does. Some paths always require another approval — anything marked as sensitive by owners, and any CI workflow file.
审查层级完全由改动本身决定,而非取决于作者是谁。一个分类器会根据改动内容评估风险等级;另一个分类器则负责研判某项特定改动是否需要额外审批,即使表面对应的梯级未作要求。某些关键敏感路径永远需要额外的人工审批——包括任何被模块负责人标记为敏感的文件,以及所有的 CI 工作流配置文件。
Only authors on the repo’s trusted list receive relaxed review requirements, and that’s generally the team that owns the repo. All others require a second person to approve. Agent approvals don’t count as human approvals. Automated review can clear a low-risk change, but it can’t stand in for a human when one is required.
只有位于仓库可信列表中的作者才能享受相对宽松的审查要求,这通常是直接负责维护该仓库的核心团队。其余所有人的提交都必须获得第二名开发者的审批。智能体给出的通过(approval)绝不能算作人工审批。自动化审查有权放行低风险改动,但当规则明确要求人工参与时,机器绝不能代替人类。
The author of the change is responsible for it, so if an agent authors a PR the operator of the agent is always counted as one of the required reviewers. A PR approval is only good for one commit. If a new commit lands that can’t be trusted (e.g. an agent pushed something, or someone resolved a merge by hand), the PR must be reapproved.
代码变更的作者始终承担最终责任,因此如果一个 PR 是由智能体创建的,那么操纵该智能体的人类开发者就会被计为必须参与的审阅者之一。此外,一次 PR 审批仅针对单次 Commit 有效。一旦推送了新的不可信提交(例如智能体又推送了新改动,或者有人手动解决了合并冲突),PR 必须重新接受审批。
6. 合并队列、特性标记与分阶段发布
The merge queue ensures that all the checks run on main with the change applied. This prevents merging two successful PRs into a broken main. Typically, new features are rolled out behind a feature flag, with Anthropic employees getting access first. Because we use the product extensively, we often notice regressions before our users do.
合并队列(merge queue)确保所有检查项都是在将改动应用到最新的 main 主干分支后再执行验证。这能够有效防止「两个单独看都测试通过的 PR,合并后却把主干打崩」的经典困局。通常情况下,新特性都会置于特性标记(feature flag)保护之下,首先向 Anthropic 内部员工放量试用。由于我们自己在高频深度使用该产品,往往能在用户察觉之前率先发现体验回退(regression)。
When we roll out publicly, changes go to the latest channel first, and the stable channel trails behind.
当我们面向公众发布时,改动会首先推送到最新的 Canary/Latest 尝鲜通道,而稳定版(Stable)通道则稍后跟进。
7. 快速反馈与一键回滚
Some bad merges will inevitably make it through. This is our last line of defense, focused on identifying these as quickly as possible. Changes behind feature flags can be disabled without deploying.
无论防线多么完备,个别有缺陷的合并终究不可避免地会侥幸溜过。这是我们的最后一道防线,核心聚焦于以最快速度发现问题。由特性标记控制的变更甚至无需重新部署,即可在秒级直接关闭。
Claude Code runs a weekly on-call rotation and any incident reviews involve looking back to see what layer should have caught the problem. It’s still up to the author and on-call to notice bad merges, in addition to monitoring the revert and incident dashboards. We don’t yet have circuit breaker mechanisms that adjust approval requirements based on these, but it’s something we’re looking into as we’re making progress toward less human intervention in merging.
Claude Code 团队保持着每周值班轮换机制(on-call rotation),任何故障复盘都会倒查:这起问题原本应该在哪一层检查被拦截下来?除了密切监控回滚与事故仪表盘之外,发现不良合并主要依然依赖作者和值班人员的敏锐洞察。我们目前尚未引入根据监控指标自动动态调高审批门槛的熔断机制(circuit breaker),但在逐步向「减少合入环节人工干预」演进的过程中,这正是我们正在积极探索的方向。
One team member noted that slowing down and reducing output can actually improve accuracy, but that’s mostly because the amount of work being done decreases overall. Our priority is really on improving our ability to identify and correct issues quickly.
团队中有一位成员曾指出,放慢节奏、减少产出确实能提高准确率,但这在很大程度上只是因为整体工作总量减少了而已。我们真正的战略优先级,始终是全面强化以极快速度定位并纠正问题的能力。
我们如何持续改进代码审查系统
Our code review process is an ongoing cycle of improvement:
我们的代码审查流程是一套持续自我演进的闭环:
We use incidents as an evaluation metric. The team collected incident-causing PRs, their fix-forwards and reverts, and had the engineers who understand the codebase verify the location and correctness of each bug. The review system is evaluated daily against this collection.
我们将真实历史事故作为核心评测指标(evals)。团队系统化地收集了所有曾引发事故的 PR、它们对应的热修复补丁(fix-forwards)以及回滚记录,并组织最熟悉该代码库的资深工程师逐一核验每个 Bug 的确切位置与正确解法。审查系统每天都会对照这批事故数据集进行日常评测回归。
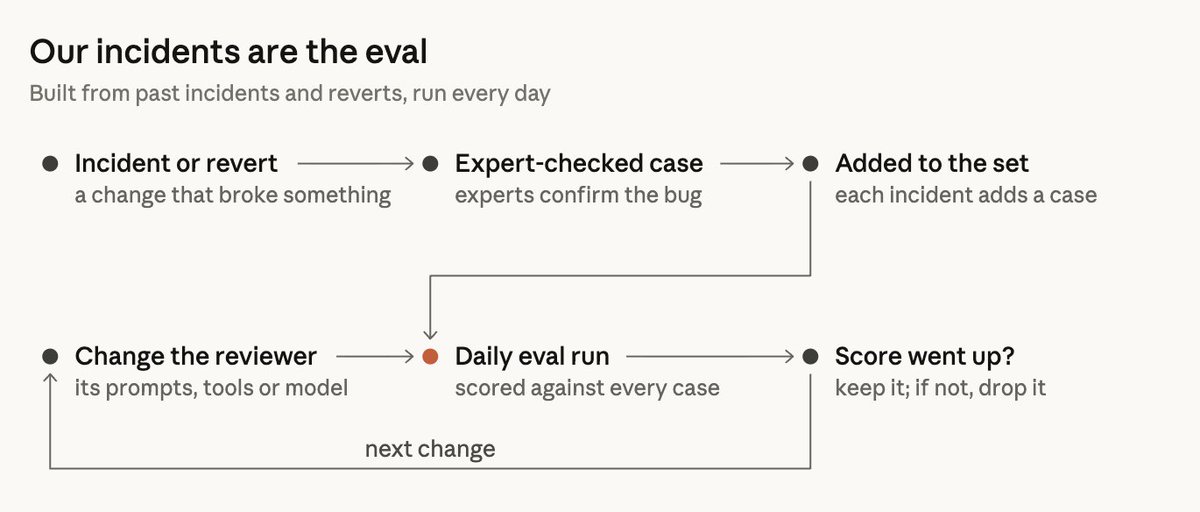
图 D:真实事故就是最好的评测集(FIG D: Our incidents are the eval)
Every incident adds to the collection and every change to the review system is evaluated against the entire collection.
每一次发生新事故,这套数据集就会扩充一条案例;而审查系统自身的每一次提示词或逻辑改动,都必须跑完整套数据集来进行全面评测。
To measure noise, we observe how humans react to the review comments. It’s easy to improve our bug-finding rate if we’re okay with reporting lots of non-bugs, so this needs to be regulated. We categorize each review comment into how the person on the PR handled it: fixed the issue, rejected it, clarified it as intentional, or decided it didn’t matter. Additionally, we run the review system on PRs we know to be clean and observe how often the system reports something that would have resulted in a harmful change.
为了量化审查噪音,我们密切观察人类开发者对审查意见的真实反应。如果容忍系统大肆乱报非 Bug 问题,想要盲目提高 Bug 检出率是轻而易举的,因此噪音必须受到严格约束。我们根据 PR 当事人的处置方式对每条审查意见进行归类:采纳并修复、直接驳回、解释为刻意为之的设计、或者认为无关紧要。此外,我们还会特意在已知干净无瑕的 PR 上运行审查系统,观察它报告那些可能诱导有害变更的错误频率。
Our stated priorities are first, detecting real bugs, and second, reducing the number of review cycles.
我们明确声明的两大优先级依次为:第一,精准捕获真实的 Bug;第二,最大程度减少反复审查的轮数。
It’s more costly for an author to have to deal with a review comment when they’re an agent. It only takes a second for a human to dismiss a nit, but when an agent has to address it, this results in another commit, and another cycle of review.
当代码作者是智能体时,处理审查意见的代价反而要高得多。对于人类来说,随手忽略一条细枝末节的琐碎意见(nit)只需一秒钟;但当智能体被迫去响应它时,就会触发一次全新的 Commit,并再次引来一整轮新的漫长审查。
The review process must converge. It’s possible for an agent author and an agent reviewer to cycle forever. We observed one PR in our CLI project cycle more than fifty times overnight, due to the back-and-forth between the agent author and the agent reviewer. This cycle was stopped manually, but it could have gone on indefinitely.
审查流程必须能够收敛(converge)。智能体作者与智能体审查器之间极有可能陷入永无休止的死循环。我们曾在 CLI 项目的一个 PR 中亲眼目睹过:由于智能体作者与智能体审查器之间的反复拉扯,短短一夜之间循环往复了 50 多轮。虽然这个死循环最终被人工手动叫停,但如果不加干预,它原本可以无限死磕下去。
When we ran git blame on what the review system kept flagging, ~59% of it was code that had been there since its first pass. Essentially, the review system was rarely finding new bugs, but finding a few more old ones on each cycle.
当我们对审查系统反复纠缠报错的代码运行 git blame 时发现,约 59% 的内容其实从第一轮审查起就一直存在于代码中。换句话说,审查系统在后续轮次中几乎没能发现什么新引入的 Bug,而只是在每一轮里又把陈旧存量问题多翻出了一点而已。
We made this worse because we had gotten into the habit of running several review cycles by default, because each cycle can find a different bug. While it can be useful to iterate through several review cycles for a high-risk change, it’s not needed for every PR. Our team started tracking the number of cycles-to-pass in addition to recall, and updated re-review to:
我们自己一度加剧了这一问题,因为我们曾习惯于默认运行好几轮审查循环,寄希望于每轮能挖出不同的 Bug。虽然对于高风险改动来说多轮迭代确实有益,但绝非每一个 PR 都需要这种待遇。于是,我们的团队在召回率之外,开始同步追踪「通关所需轮数」(cycles-to-pass),并对二次审查(re-review)机制进行了升级:
Limit the number of cycles. The review system asks the author to re-evaluate the approach after three cycles. Limit re-review to just diff after the initial cycles. Specify the class of bugs, so the author can correct all of them, not just one line. Avoid re-reporting issues already observed. The review agents are also run on the current codebase overnight, helping us identify historical bugs before they propagate.
严格限制审查轮数:在三轮审查后,系统会主动提示作者重新审视当前的实现路径;在初始轮次之后,将复审范围严格限制在最新的 diff 之上;明确指出 Bug 的类别,以便作者能够一次性系统修正所有同类问题,而非逐行缝缝补补;避免重复报告此前已经指出过的已知问题。此外,审查智能体还会在夜间对当前代码库的主干全量运行,帮助我们在历史 Bug 扩散之前将其及早揪出。
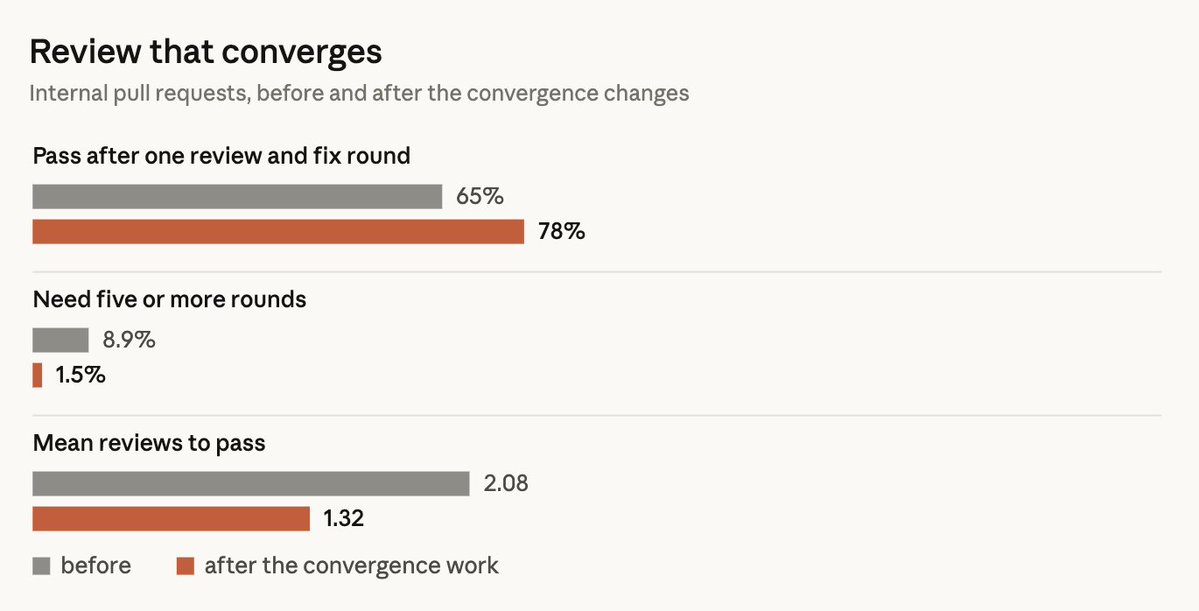
图 E:实现快速收敛的代码审查(FIG E: Review that converges)
Reduction in the average number of review rounds per internal pull request after Convergence.
引入「收敛机制」后,团队内部每个 Pull Request 的平均审查轮数显著下降。
人在环内:保留给人类的关键职责
Having a senior engineer stop working to review a common error is an expensive process compared to automating that process. Human reviewers are still essential for some tasks:
与将流程自动化相比,打断一位资深工程师手头的工作去肉眼排查常见低级错误,是一件极其昂贵的奢侈浪费。然而,在以下关键任务中,人类审阅者依然不可或缺:
-
Should we even build this? Deciding whether or not to build something, setting the vision, taste, and goals for the product.
-
这东西到底该不该做?决定要不要做某项功能,把控产品的远景方向、设计品味(taste)与核心目标。
One team that claims they have solved the bottleneck of code review still performs human review for changes from outside the team to ensure that it is the right thing to build.
某个声称自己已经彻底解决了代码审查瓶颈的团队,在面对来自团队外部的代码改动时,依然坚持进行人工审查,以确保这确实是值得构建的正确方向。
-
Auditing dangerous code (billing, auto-updater, CI workflows).
-
审计高危核心代码(如计费逻辑、自动更新程序、CI 工作流配置等)。
-
Architecture review, because those choices set the conventions others follow.
-
架构设计审查,因为架构上的技术选型将沉淀为团队其他成员必须遵循的代码约定。
-
Verifying proofs (test output, commands run, screenshots, reviewer comments). If you can’t describe what the checks would miss, don’t ask for a 👍, you need a real review!
-
校验确定性证据(测试输出结果、执行过的命令日志、界面截图、审查机器人反馈)。如果你甚至无法说清既有检查到底会遗漏什么,就千万别只敷衍地求一个 👍 赞同表情,你需要的是一次严肃的人工深度审查!
-
Taking responsibility. A person answers for every change that ships, whoever typed it.
-
勇于承担最终责任。无论代码最初是由谁敲下键盘或由哪个模型生成,上线的每一行改动背后,必须由一个具体的人类站出来负责。
团队上下文:机器阅读之后,人类如何理解代码库?
Code review has always served the dual purpose of communicating codebase changes. Reading the diff of a colleague’s change is how people usually understand what has changed, and how the codebase works. If the bulk of the reading is done by machines, what becomes the way to learn the codebase?
代码审查历来承担着传递代码库变动的沟通纽带作用。在过去,阅读同事改动的 diff 是人们了解系统变化以及掌握代码库运作机制的最主要途径。如果阅读 diff 的大半工作都被机器代劳了,人类未来又该如何学习和理解整个代码库?
We don’t have any formal mechanism for this. No member of the team has a full mental model of Claude Code in their head, nor do we think anyone needs to. Rather, when anyone wants to learn about a piece of the codebase, they ask Claude to generate an explainer about that exact slice. It only takes a few minutes and the explainer is always up to date.
我们对此并没有建立任何刻板僵化的正式机制。团队中没有任何一个成员脑子里能装得下 Claude Code 完整的心智模型,我们也不认为有谁需要做到这一点。相反,每当有人想深入了解代码库的某个局部切片时,他们只需让 Claude 针对该确切切片实时生成一份技术解说文档(explainer)。这只需要几分钟时间,而且这份解说永远是最新的、与现状严密吻合的。
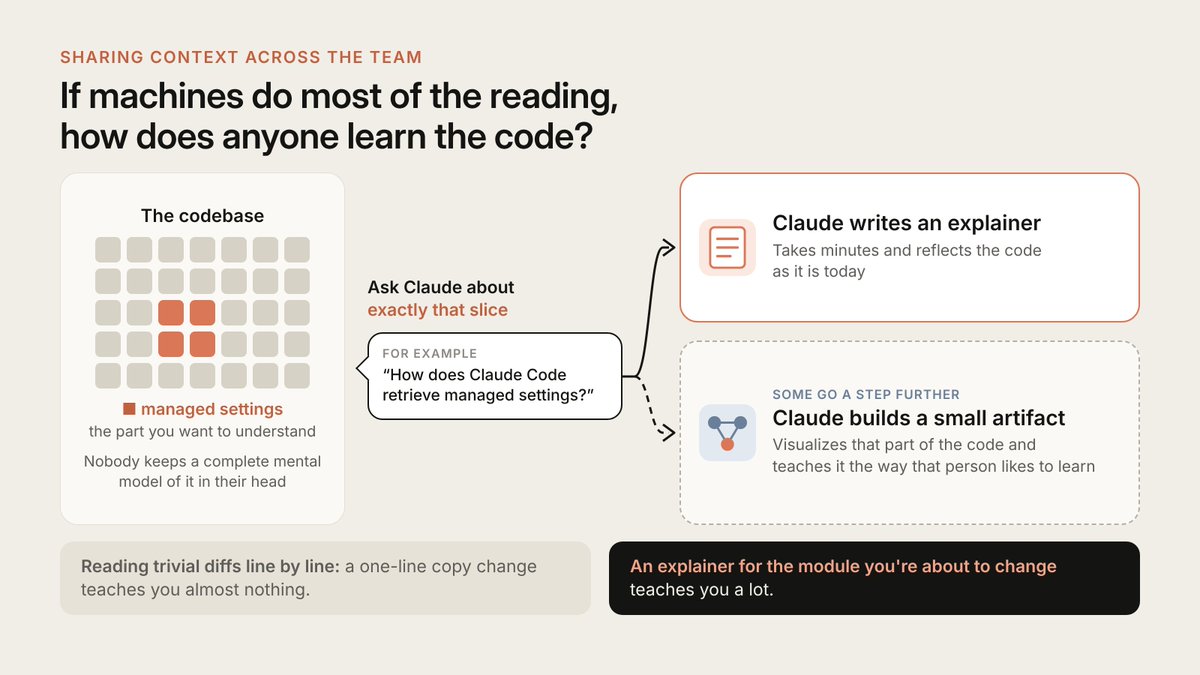
图 F:当机器承担了绝大部分阅读工作,大家该如何学习代码库?(FIG F: If machines do most of the reading, how does anyone learn the code?)
For some of us, we go the extra step and have Claude generate a mini artifact that visualizes this area and teaches it in our preferred style.
对于我们团队中的某些人,还会更进一步:让 Claude 生成一个轻量工件(artifact),将该领域可视化,并以最符合个人理解习惯的风格来生动教学。
This is a better way to focus our human attention than reading trivial diffs line by line, which teaches you very little (e.g. a one-line copy change). Creating an explainer about the module you’re going to change teaches you a lot.
相比逐行阅读琐碎的 diff,这能更高效地聚焦人类注意力。逐行阅读那些微小的改动(比如单行文案微调)几乎学不到任何东西;而为即将动手的模块专门生成一份系统解说,却能让你获益匪浅。
Plus, we’re generally open by default, working in open Slack channels, and seeing what others are building as they build it.
此外,我们团队在日常文化上推行「默认透明开放」:全员在公共 Slack 频道中协同办公,在他人动手构建的同时就能实时看到正在推进的工作。
「谁合入,谁负责」
If you merge a small or medium change, and something still goes wrong, the general expectation is that you usually fix it yourself. There are a few reasons why this doesn’t spiral out of control:
如果你合并了一个小中型改动却依然引发了问题,团队的基本共识是:原则上由你本人亲自负责修复。之所以这种机制没有引发灾难性失控,主要得益于以下几点:
-
Small changes that are easy to review, debug, and revert.
-
极小颗粒度的变更:小体积让审查、排错以及回滚变得轻而易举。
-
Everything can be reverted. Feature flags, reverts, and staged rollouts can reverse most mistakes in minutes.
-
一切皆可回滚:特性标记、代码一键撤销与分阶段灰度发布,能在数分钟内完全撤回绝大多数失误。
-
Blast radius sets the bar. More expensive code gets more eyes and validation.
-
爆炸半径决定防护门槛:潜在代价越昂贵的高危代码,获得的人工注视和验证防护力度就越强。
-
Regressions are surfaced quickly by telemetry and internal usage.
-
遥测监控与内部深度吃狗粮(internal usage)能以极快速度让体验回退无所遁形。
-
It’s not a blame game. The person who fixes the issue owns it because they have the most context. Incident reviews consider the system.
-
绝非问责推诿:负责修复问题的人之所以主导处理,是因为他们在当下拥有最充沛的上下文。故障复盘永远着眼于整个系统机制的改进,对事不对人。
-
Plus, much of the team shares responsibilities by working in open channels. Anyone can see what others are building, join in on the conversation, or have Claude look for gaps. Feedback also comes from non-code owners. That openness is a big part of why quality stays high without a gate on every line.
-
此外,大部分团队成员都在公开频道中分担协同责任。任何人都能看到其他人正在构建的内容、随时参与讨论、或者指示 Claude 帮忙探查漏洞盲区。反馈甚至常常来自非代码所有者。这种高度的开放性,正是我们在无需对每一行代码设卡的前提下依然维持极高品质的关键根基。
适时调头与果断放弃
With agents, it is cheap to start new work, but sometimes you shouldn’t. This typically arises when someone in the channel calls out the proposed change as an invalid path (citing previous decisions or suggesting a better path), and the author either closes the PR or changes the implementation.
借助智能体,开启一项新工作的试错成本变得极其低廉,但有时你压根就不该继续往前走。这种情况通常发生在频道里有人指出提议的改动属于无效路径时(例如援引此前的架构决策,或提出更优替代方案),此时作者会毫不犹豫地直接关闭 PR 或彻底调整实现路线。
Because it was easy to write the code in the first place, it doesn’t feel like a loss to close the PR. The key is to pivot early in the thread, instead of waiting until the end to make a blocking comment on a finalized PR.
正因为最初写出这批代码毫不费力,直接关闭 PR 完全不会产生沉没成本的心理痛感。这里的核心秘诀在于:在讨论的早期阶段就及早调头,而不是等到 PR 全部定稿之后才跑去丢下一句阻断合入的冷冰冰评论。
落地指南:如何在你的团队中实践?
Most of the components of this approach are already available to your team.
这套方法论中的绝大部分组件,其实如今已经可以直接在你的团队中取用落地。
PR 提交前阶段
-
Give the agent a checklist of checks it can run. List these checks in a short CLAUDE.md file
-
为智能体配备一份它可以自主运行的检查清单。将这些检查精炼地列在
CLAUDE.md文件中。 -
Set up the agent to call formatters and linters via hooks
-
通过钩子(hooks)机制,配置智能体在合适节点自动调用代码格式化工具与 linter。
-
Run /code-review and /security-review locally or have a new-context subagent review the changes
-
在本地运行
/code-review与/security-review命令,或者唤起一个拥有全新独立上下文的子智能体来交叉审阅改动。 -
Create a REVIEW.md, and use it to track recurring review issues
-
创建
REVIEW.md文件,用于专门沉淀和跟踪那些反复出现的审查高发问题。
针对每个 Pull Request 阶段
-
Enforce CI
-
严格强制推行 CI 持续集成流水线。
-
Update your PR template with “Testing”, “Risk” and “How to revert”
-
更新你的 PR 模板,强制包含「如何测试(Testing)」、「风险评定(Risk)」以及「如何回滚(How to revert)」三项要素。
-
On one repo, add an AI reviewer (Code Review for Claude Code, or the Claude Code GitHub Action), and iterate on your REVIEW.md for a few weeks before rolling it out to more repos.
-
先挑选单个仓库试点接入 AI 审查器(如 Code Review for Claude Code 或 Claude Code GitHub Action),持续打磨调优
REVIEW.md数周时间,再逐步推广至更多仓库。 -
Add an automated security review
-
引入全自动化的安全审查关卡。
-
Require that all review threads be resolved before merging
-
强制要求所有审查讨论线程在合入前必须全部处置完毕(resolved)。
-
Apply review rigor according to risk: a quick pass for routine changes, and a thorough review for high-risk areas (where bugs are expensive). Code Review has Quick, Standard and Deep levels.
-
根据风险等级实施差异化审查力度:常规改动快速放行,高危领域(出现 Bug 代价极高)实行严苛深审。Code Review 提供了 Quick、Standard 与 Deep 三档模式。
-
Limit the number of review rounds, and after a few rounds, just review the new diff.
-
严格限制审查循环的轮数;在经过前几轮审查后,后续复查仅聚焦于新产生的 diff。
审批把控阶段
-
Define risk levels, which are set based on the change, not the author. Start strict, and progressively relax as you see evidence.
-
明确定义风险等级,且风险判定完全基于变更内容本身,而非基于作者。初期从严设卡,随着数据与成效的验证逐步适度放宽。
-
Reserve lenient approval paths for trusted authors.
-
仅对受信任的作者群体保留相对宽松的免审/单人审批通道。
-
Bot approvals cannot be used to satisfy a required approval. Dismiss any approvals when new commits are pushed.
-
机器人/智能体的审查通过绝对不能抵充必须的人工审批。一旦推送了新的 Commit,立即自动撤销先前的所有审批。
-
Designate humans as the approvers for code and policies controlling auth, billing, CI, and release workflows, as well as installers. Use CODEOWNERS and branch protection for this.
-
对涉及身份认证、计费逻辑、CI 流水线、发布工作流以及安装包的核心代码与策略,指定人类作为法定审批人。借助
CODEOWNERS和分支保护规则(branch protection)落地推行。
合并与合并后阶段
-
Set up a merge queue
-
建立合并队列(merge queue)机制。
-
Experiment with feature flags
-
积极采用特性标记(feature flags)进行发布解耦。
-
Launch to internal users first
-
坚持内部员工深度试用优先(狗粮先行)。
-
Roll out in stages
-
采取分阶段逐步放量(staged rollout)的灰度发布策略。
-
Create a one-step revert mechanism
-
打造一键秒级回滚机制。
-
Build a set of evals by logging incidents and reverts
-
将历史事故与回滚案例沉淀为成套的标准评测基准(evals)。
-
Rescore the reviewer any time you change its prompts, tools or model
-
无论何时对审查系统的提示词、工具集或底层模型做出改动,都要对照评测集重新打分验证。
-
Track human effort, using reverts and incident rates as guardrails
-
严密追踪人类工作量投入,并以代码回滚率与线上事故率作为核心守门护栏。
未来的演进方向
Code Review was announced with the intention that the final approval decision would still be made by a human. All the product does is post its findings. But in our own repos, we are going further: Owners are deciding which low-risk changes can be merged automatically when the automated checks pass. And this boundary will continue to evolve.
Code Review 最初对外发布时的预设是:最终的审批决策依然交由人类拍板,产品本身仅负责陈列发现的问题。但在我们自己的内部仓库中,我们正在走得更远:代码所有者们正在划定边界,决定哪些低风险变更只要全部通过自动化检查,就可以直接全自动合入。随着时间推移,这条人机分工的边界还将继续向前演进。
So whenever our reviewers miss something, we ask ourselves what wasn’t in the model’s context, and turn that into a CLAUDE.md file, a skill or a new check. And we haven’t changed our goal: To reduce the amount of human effort per change while keeping our revert rate no higher than it is now.
因此,每当我们的审查器漏掉了什么问题时,我们都会深刻反思:到底是哪些关键信息没有进入模型的上下文?然后立即将其转化为 CLAUDE.md 中的规范、一项新的 Agent 技能、或者一条全新的自动化检查规则。我们的终极目标始终坚如磐石:在确保代码回滚率不高于现状的前提下,大幅削减单次代码变更所消耗的人类精力。
So if you also allow agents to create pull requests, please let us know what checks you’ve automated, what requires a human, and what we’re getting wrong.
所以,如果你也已经开始允许智能体在你的代码库中创建 Pull Request,热切欢迎你告诉我们:你们把哪些检查做成了自动化?哪些环节依然坚决保留人类把关?以及在我们当前的实践中,有哪些地方是你觉得做得不妥的?
A rewrite of our original article and checked with Pangram.
本文由我们在 claude.dev 上的早期文章重写扩充而成,并经由 Pangram 进行了校对。